Möbius: A Unified Motion-Language Model
Bridging Understanding and Generation

Jiazhi Shu1,2,*Chengfeng Zhao1,*Jinyi Wang2,†Yubo Zhao1,2Zhiyang Dou3

Ronghui Li2Yu Lu2Xinwei Jiang2Zijiao Zeng2,‡Yuan Liu1,‡

1The Hong Kong University of Science and Technology

2Tencent Games Motus

3Massachusetts Institute of Technology

*Equal contribution.†Project lead.‡Corresponding authors.

01 / MOTION GENERATION

Text-to-Motion Generation

15 precomputed comparisons

02 / MOTION UNDERSTANDING

Motion-to-Text Understanding

11 selected samples

03 / MOTION COMPLETION

Motion Completion

Give a partial motion, with or without a text prompt. Möbius completes the missing motion.

4 tasks · 32 selected

04 / MOTION EDITING

Motion Editing

7 selected samples

METHOD OVERVIEW

Möbius Pipeline

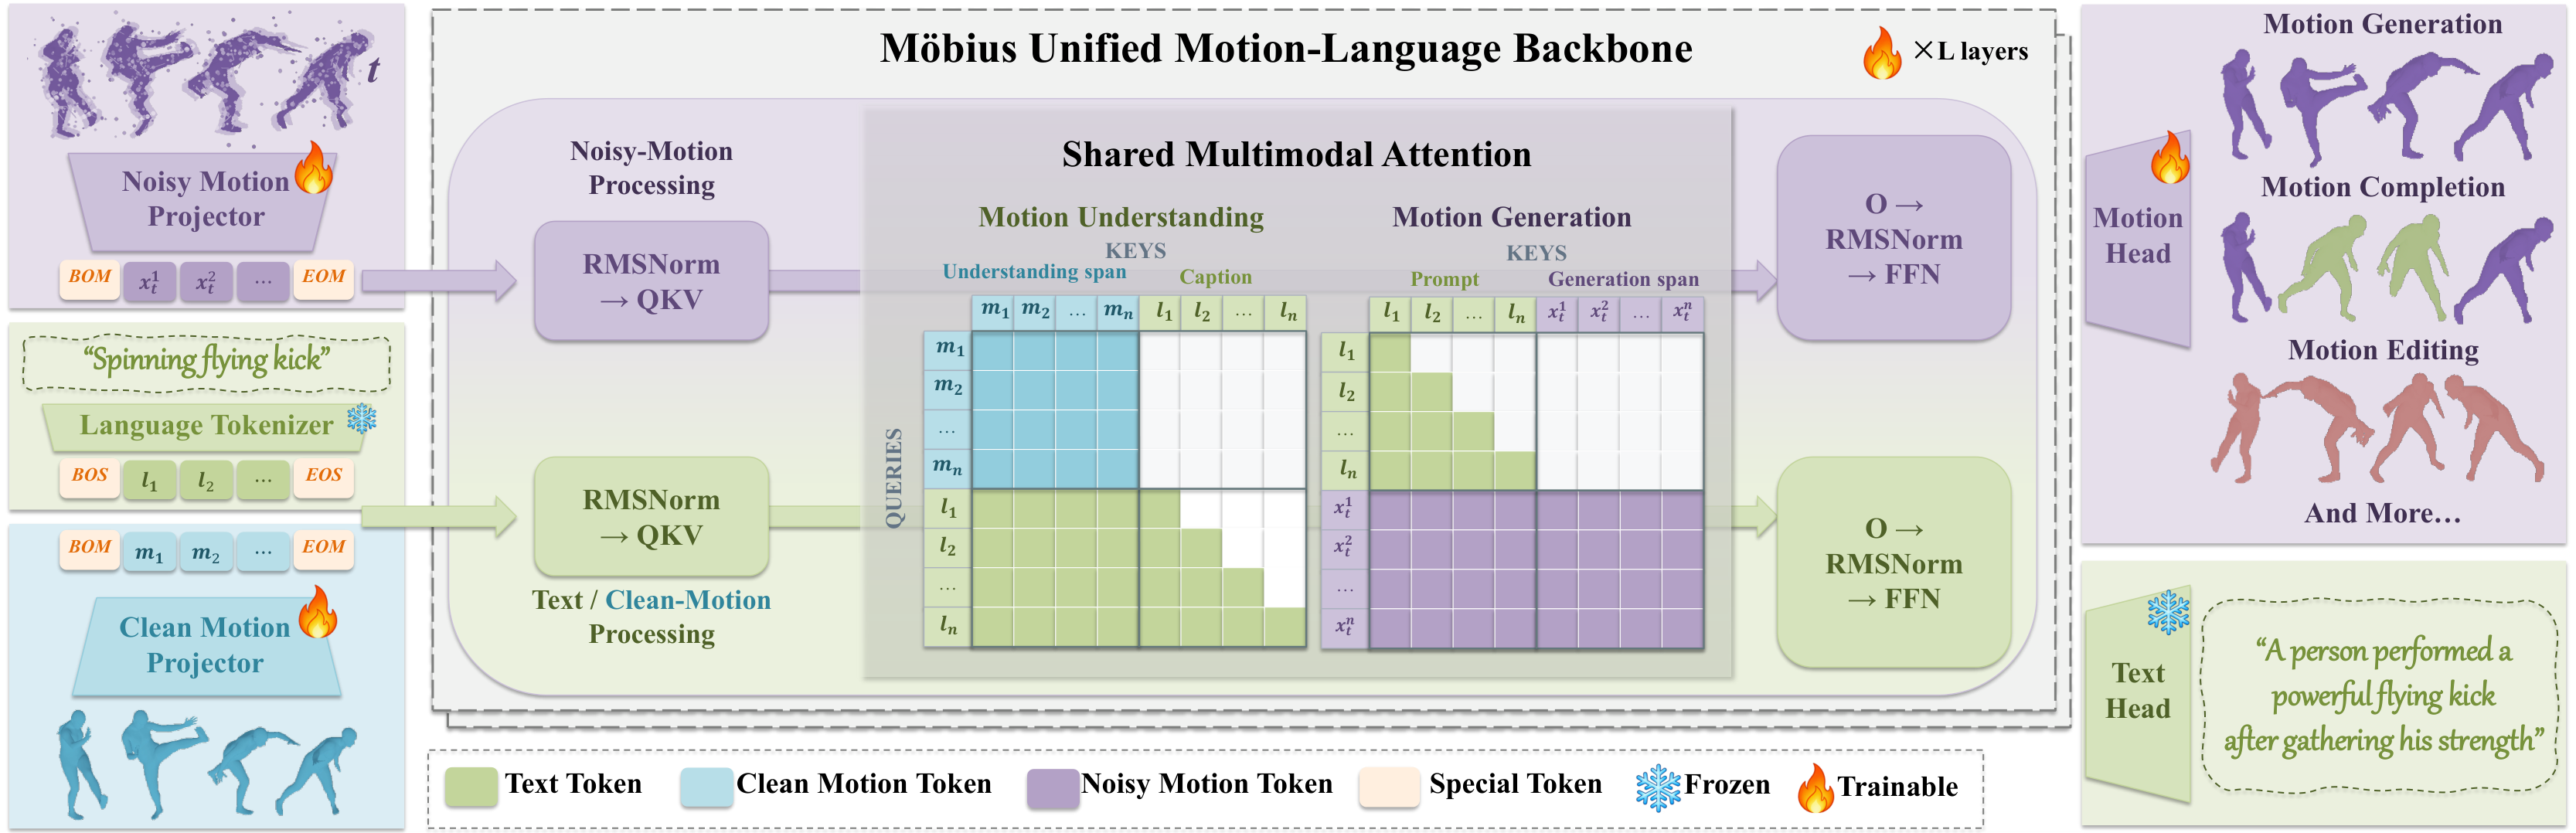
Möbius architecture: language tokens, clean motion, and noisy motion share a unified backbone for motion understanding, generation, completion, and editing.
Pipeline overview. A unified motion-language backbone connects text and motion through shared multimodal attention, supporting motion understanding, generation, completion, and editing.View full-resolution PDF ↗

QUANTITATIVE RESULTS

Benchmark

Results on the HumanML3D test set.

GENERATION

Text-to-Motion

MotionStreamer MS-272 evaluator

MethodTaskR@1 ↑R@2 ↑R@3 ↑FID ↓MMDist ↓Diversity →
GT--0.77030.90300.94420.000014.878527.7705
Trained on HumanML3D
T2M-GPTGen.0.55160.70560.778825.491319.091225.5949
MoMaskGen.0.64040.79740.860921.072918.121625.9789
MDMGen.0.52080.69370.770135.516919.424625.3383
MotionStreamerGen.0.63030.78650.849812.211016.581027.4637
MotionGPTUnified0.49400.63520.694423.681119.678125.5410
MotionGPT3Unified0.67090.82420.881720.991317.566425.6889
Ours (0.6B)Unified0.82090.93970.96706.129113.997327.6107
Trained on large-scale dataset
Go to Zero (3B)Gen.0.74010.87720.922923.755015.380626.6340
HY-Motion (1B)Gen.0.78990.91770.951613.519414.774827.4183
Ours (1.7B)Unified0.79680.92260.952410.664214.744127.4649

Bold and underline indicate the best and second-best results within each training-data group. Diversity is compared with ground truth.

UNDERSTANDING

Motion Captioning

TM2T evaluation protocol · raw captions

MethodBLEU-1 ↑BLEU-4 ↑ROUGE-L ↑CIDEr ↑BERT ↑R@1 ↑R@2 ↑R@3 ↑MMDist ↓
GT1.00001.00001.00004.51651.00000.50680.70640.80412.9784
TM2T0.49120.07600.38080.17190.32150.51800.71780.80792.9584
MotionGPT0.46050.12100.38490.34090.33880.50870.68800.77763.1121
MotionGPT30.53830.16050.41650.40770.34250.53330.71780.80432.8533
UniMuMo0.44880.12710.35600.31140.45170.51620.70320.79842.9658
Ours 0.6B (ML3D only)0.56640.20320.46360.57540.45410.60560.79360.87612.4693
Ours 1.7B (large-scale)0.58740.21050.47250.58360.46570.61520.80860.88622.4143

Bold and underline indicate the best and second-best model scores.